 Tuna Industrial Platform
Guide
What industrial AI needs before the model: context, quality and governance
Most industrial AI projects stall before a model is trained. A practical account of the three prerequisites that decide the outcome: asset context, data quality and decision governance.
What industrial AI needs before the model: context, quality and governance
Most industrial artificial intelligence projects do not fail because the algorithm was wrong. They fail earlier. The plant could not say what a signal meant, could not show that the data could support learning, or could not agree who was allowed to act on the output. Context, data quality and governance are not paperwork around the model. They decide whether the model is worth anything.
This article describes what should exist before a model is trained, and in what order to build it. It draws on NIST's AI Risk Management Framework and operational technology guidance, the OPC UA specification, and two peer-reviewed studies of machine learning practice. Every number below states its assumptions, and none describes a Tuna Industrial Platform deployment.
The short version is uncomfortable for anyone funding a pilot. The model is the cheapest and most replaceable component. Almost everything that makes it useful is built around it, and most of that work is not machine learning.
The model is the smallest part of the system
Two strands of published research reach the same conclusion from different directions.
Interviews with 53 practitioners working in high-stakes AI found that data problems rarely stay where they start. The authors describe data cascades: compounding events in which a defect introduced at collection surfaces much later as a model nobody trusts. They report a 92 per cent prevalence across the cases they studied (Sambasivan and colleagues, 2021).
A review of machine learning operations reports the same pattern from the engineering side: the field has concentrated on building models rather than production-ready products, and many proofs of concept never reach production (Kreuzberger, Kühl and Hirschl, 2023).
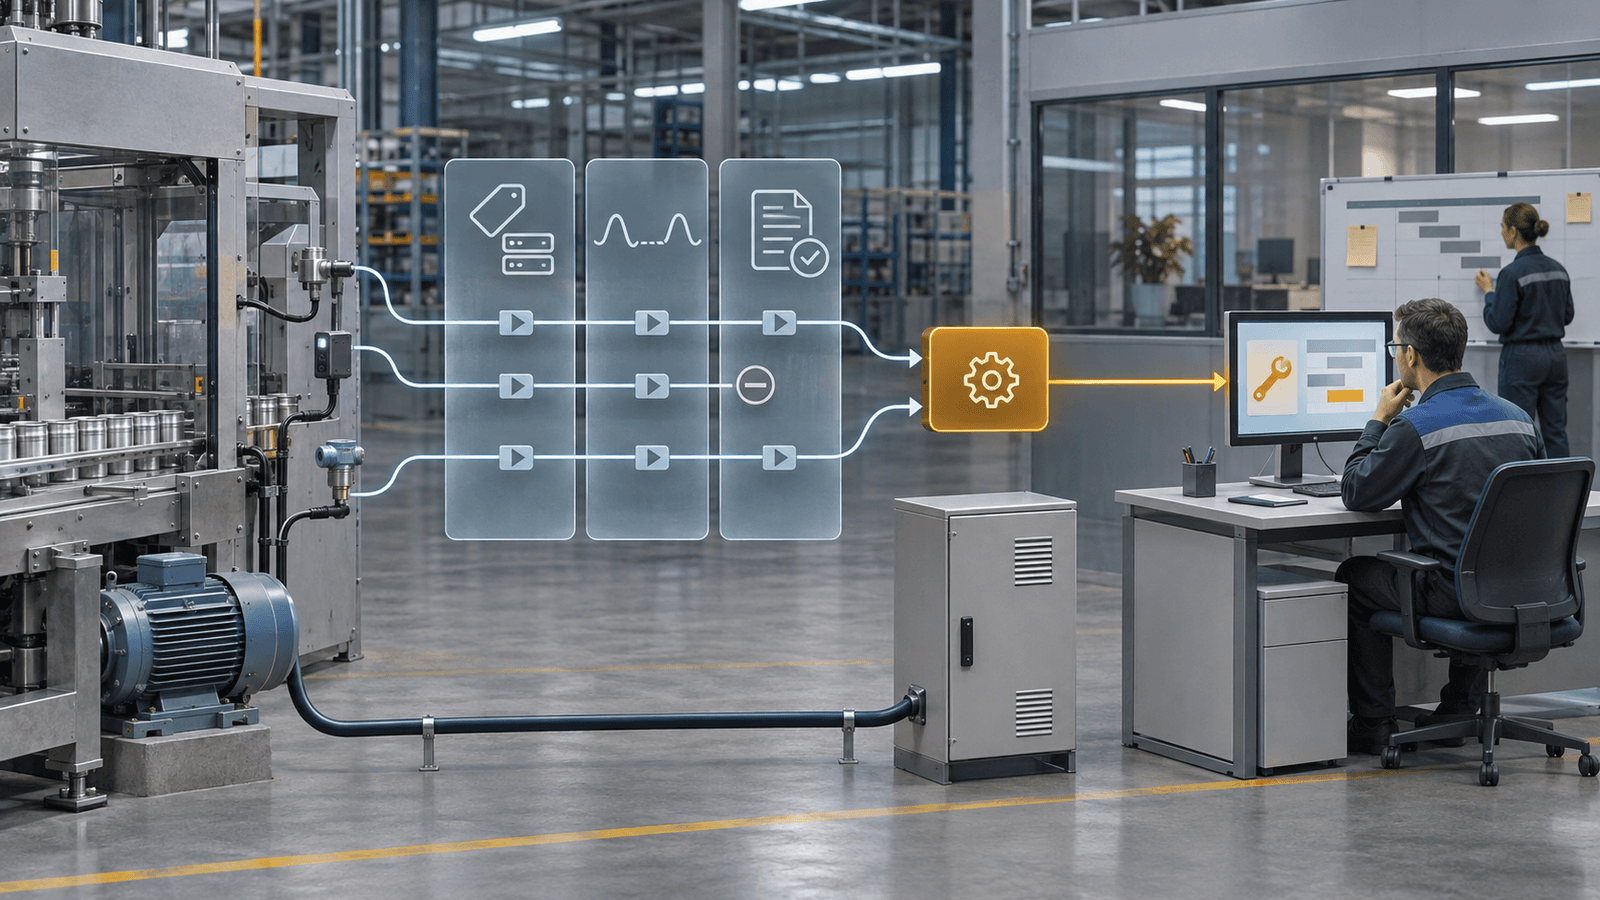
In plant language, a model is a function that maps inputs to a number. Something must supply the inputs, decide what the number means, act on it, notice when it stops being true, and retire it. Those somethings are an asset register, a historian, an event taxonomy, a maintenance process and a person with authority. Without them the model is not wrong. It is irrelevant.
Prerequisite one: context
Context is what turns a number into an observation: which asset produced it, in which operating state, in which unit, at what time, with what quality, and for which decision it is evidence. Strip those away and a time series becomes a shape without a subject.
A number without a state is not an observation
A vibration reading on a motor means different things when the machine is warming up, at full load, idle, or mid-changeover. A pipeline that stores only the value and a timestamp leaves the model to infer the state from time of day. It will learn the shift pattern instead of the machine, and it will look excellent in testing, because shift patterns are highly predictable.
This is the layer OPC UA was written for. Part 1 specifies an information model to represent structure, behaviour and semantics, and lets servers expose type definitions and metadata that clients query at runtime (OPC 10000-1, sections 4.1 and 4.3). That is a modelling capability, not a populated model. The standard supplies a way to describe an asset, a tag, a unit and a relationship. Only the plant can supply the content, and the content is what takes a year.
For most manufacturers the practical artefact is an asset and tag register that survives contact with maintenance: identifiers that match the maintenance system, tag names a new engineer can read unaided, units recorded once, and operating modes stored as data rather than inferred. Where an ISA-95 style hierarchy already exists, this register is where its levels acquire real names.
The failure definition is the harder half of the label
Supervised maintenance models learn from events, and events are recorded by people at the end of a shift. That single fact drives most label quality.
Four questions need written answers before labelling starts. When did the failure begin: first alarm, first rejected part, rate drop, or call to maintenance? Does a planned replacement count? Does a no-fault-found intervention count, and as what? Who may overrule the recorded code, and where is the correction stored?
NIST treats this as a documentation duty. Subcategory MAP 2.3 asks organisations to document data collection and selection with respect to availability, representativeness and suitability, which is a formal way of asking whether the labels mean what the model will assume (NIST AI RMF 1.0, MAP 2.3).
Test the decision before the model
Before choosing an algorithm, name five things: the decision, the person who makes it, the action that follows, the time available, and the relative cost of the two error types.
If the output is "this bearing will probably fail within fourteen days", the decision is "schedule a replacement inside the next planned stop". The false negative is an unplanned line stop. The false positive is a technician inspecting a healthy bearing. Those costs are asymmetric, so a single accuracy figure says little about usefulness.
NIST places this in its MAP function, which establishes context to frame risk and warns that without contextual knowledge risk management is difficult to perform (NIST AI RMF 1.0, MAP 1.1).
Prerequisite two: data quality
Data quality is not one property. Four defects account for most of the damage in industrial time series, and each has a cheap diagnostic.
Gaps. Network drops, controller restarts and historian outages leave holes. A model trained on dense data and served on gapped data is being asked a different question from the one it learned. The diagnostic is a gap census per tag per shift, recording the cause rather than only the duration.
Wrong values. A transmitter drifts, or a gateway repeats its last value after a fieldbus failure. The second is dangerous because the number stays plausible. Frozen-value detection, meaning identical consecutive readings sustained beyond a physically plausible duration, catches most of it.
Misalignment. Clocks disagree between controller, historian and execution system. Seconds are harmless for a trend and fatal for attribution: a failure attaches to the wrong production order, and the model learns a mislabelled context. The diagnostic is a periodic offset audit across the three systems.
Label decay. Downtime reason codes drift as shift teams change. A code meaning "mechanical" in year one may cover another failure family by year three. Only sampling recent records and reading them detects this.
One design rule covers much of the risk: preserve the quality flag the interface already provides. Many industrial interfaces attach a status or quality indicator to every value, and many pipelines discard it at the first aggregation step, because averaging is easier than reasoning about validity. An average of good and bad values is neither. Decide whether unqualified values are dropped, flagged or held, and record the decision.
Volume is not quality
Storage is cheap enough that volume feels like progress. Assume 30 machines, 40 signals each, 1 Hz sampling, 8 bytes per value. That is 1,200 signals and 9,600 bytes per second, or roughly 829 megabytes a day, about 303 gigabytes a year. This is illustrative arithmetic, not a measurement of any plant.
Three hundred gigabytes a year is a manageable storage problem. Sixty labelled failure events a year is not a manageable labelling problem, and the two are unrelated. Trimming the signal list to save storage can also delete the evidence, because a defect signature may sit at a frequency a one-second average erases. The question is which signals carry the signature, and at what rate they must be sampled to keep it.
A worked example: what thirty machines give you
The arithmetic is illustrative, with every assumption visible.
Assumptions: 30 machines, one failure mode, two recorded events per machine per year, 24 months of usable history, and the most recent 12 months held out so that evaluation is not contaminated by the training period.
- Events per year: 30 multiplied by 2 equals 60.
- Events across 24 months of history: 120.
- Training set, first 12 months: 60 events.
- Test set, recent 12 months: 60 events.
- If two failure modes must be separated: 30 training examples per class.
Suppose the model detects 45 of the 60 test events. Measured recall is 75 per cent, and the 95 per cent Wilson confidence interval is about 63 to 84 per cent. Had the test set held only 10 events and the model caught 8, the point estimate would be 80 per cent and the interval roughly 49 to 94 per cent. The interval, not the point estimate, is what a planner experiences as reliability.
The same arithmetic explains why the holdout must be time-based and touched once. With 30 examples per class, any threshold tuned against the test period yields a number that cannot be reproduced. The honest output at this scale is a range, a stated threshold, and an explicit account of what the plant does not know.
Prerequisite three: governance
NIST organises its framework around four functions: govern, map, measure and manage. Govern is cross-cutting, infused throughout risk management and enabling the other three, with categories covering policies, accountability structures, an inventory of AI systems and safe decommissioning (NIST AI RMF 1.0, section 5.1). The framework is voluntary: a management-system template, not a certificate.
In a plant, governance reduces to questions needing named answers before a pilot starts. Who owns the model once the project team leaves? Who may stop or slow a line because of its output? What does the operator do when the model is unavailable, and has that fallback been tested? Who approves a retrain, and what triggers one? When, and by whom, is the model retired?
Why the OT constraint changes the design
NIST's operational technology guidance describes conditions most data science teams have never worked under. Operational technology is generally time-critical, with acceptable delay and jitter set by the installation. Control system outages are often unacceptable and must be planned days or weeks ahead, and exhaustive pre-deployment testing is essential. The primary concerns are safety, fault tolerance, compliance, equipment loss and damaged product, not data confidentiality (NIST SP 800-82r3, section 2.4).
Two design consequences follow. A model that retrains weekly and deploys continuously is a change-management problem before it is a data science problem, because deployment changes a production system that may not be restartable on demand. And NIST recommends segmenting information technology from operational technology and permitting only explicitly authorised traffic between segments, typically through a demilitarised zone (NIST SP 800-82r3, section 5.2.3.1). A model needing a live write path into the control network has to survive that architecture, and in most cases should not have one. Read from the historian, write to the maintenance system, leave the control loop alone.
The model as a controlled document
The governance question that decides long-term value is simple: can you reconstruct, two years later, why the model produced a given recommendation? That needs a version identifier, a snapshot of the training data and its date range, the evaluation record with its test protocol and uncertainty, the decision supported, the approval, and the rollback path.
This is ordinary machine learning operations practice. The MLOps literature describes metadata tracking and lineage for every workflow task, including parameters, performance metrics and the data and code used, so that runs remain traceable, and describes continuous monitoring as periodic assessment of data, model, code, infrastructure and serving performance (Kreuzberger, Kühl and Hirschl, 2023).
In a plant, monitoring inputs matters as much as monitoring outputs. A model fed by a drifting sensor is not degraded gracefully. It is confidently wrong, and stays confidently wrong until someone notices that its accuracy claim no longer matches the shift reports.
The order of work
The sequence below avoids rework. Every item is cheaper before the model exists than after.
- Write the event and failure taxonomy, with start and end definitions and a rule for planned work.
- Build the asset and tag register, with units and operating modes stored as data.
- Fix time synchronisation across controller, historian and execution system, and document retention.
- Decide the quality-flag and gap policies, and implement them where data enters the platform.
- Name the decision owner, the action protocol and the fallback.
- Establish a trivial baseline, such as a fixed threshold or an age-based rule, and publish its performance first.
- Write the evaluation protocol, including a time-based holdout and the decision threshold.
- Only then train a model, and compare it against the baseline rather than against nothing.
Step six is the one most often skipped and the one that protects the budget. If a threshold rule already catches 40 of 60 events with acceptable false alarms, a model catching 45 has marginal value that must be argued against its operating cost.
Where this goes wrong
The model as a substitute for a maintenance regime. Predictive maintenance does not repair a plant with no preventive maintenance. If lubrication intervals are missed and spares are unavailable, a forecast changes the paperwork, not the outcome.
Governance theatre. A risk register nobody reads and an approval that is always granted are worse than no process, because they create the appearance of control while removing the incentive to build real controls.
Transferred benchmarks. Vendor accuracy figures come from another plant, another definition of failure and another operating regime. The only defensible benchmark is the plant's own baseline on its own holdout period.
Automation bias. A planner who approves every recommendation is not a human in the loop; the loop has closed by habit. Periodic review of overridden cases is the only way to keep the check real.
Regulatory assumptions. Obligations depend on jurisdiction, sector and use. The NIST framework is explicitly voluntary, and this article makes no claim about which rules apply to a given plant. Confirm any regulatory position with qualified advice before relying on it.
Conclusion
The prerequisites for industrial AI are not exotic. They are the asset register nobody finished, the failure definitions nobody agreed, the clock offset nobody measured, and the question of who may act that nobody asked. Each is inexpensive alone and expensive once a model depends on it.
A plant that answers those questions first usually discovers that it needs a smaller model than it planned, serving a narrower decision, with a shorter path from output to action. That is not a disappointing result. It is the difference between a pilot that ends in a slide and a system still running three years later.